Platform
One platform for every cluster your research runs on.
Infrastructure, Kubernetes and Slurm clusters, and the work that runs on them, in one console. In our cloud or on your own infrastructure.
One console, many clusters.
A project can hold several Kubernetes and Slurm clusters, wherever they run, and manage them all from the same place.
 Supergate Cloud console
Three layers, one console.
Every solution runs on the same clusters and infrastructure, so teams keep one login and one set of project roles across them.
Workloads
The work your teams submit.
Clusters
Schedulers we set up and run.
Infrastructure
Machines, network and storage.
- Virtual Machines
- Network
- Block Storage
- Object Storage
Built into every solution.
What each team gets wherever it works, from a Slurm job to a bio pipeline.
Projects and roles
OIDC login, invitations and project roles let project teams run clusters and jobs on their own.
Metrics and logs
See metrics, logs and health signals for each job and cluster.
Files and images
Upload job inputs, download results, and browse container registries, repositories and tags.
Costs before you run
See an estimate before you submit a bio job, then the actual usage in the same unit when it ends.
Records you can reproduce
Each bio job records the tool definition, image digest, settings, input checksums and resources used.
Agents with approval
Connect an agent over MCP. It can find bio tools and request runs, and work starts only after a person approves.
The Supergate Cloud platform
From setting up clusters to running jobs and bio pipelines.
Kubernetes and SLURM clusters
Create, inspect, scale and delete clusters, and update their add-ons.
Files and images
Upload job inputs, download results, and browse container registries, repositories and tags.
Metrics and logs
See metrics, logs and health signals for each job and cluster.
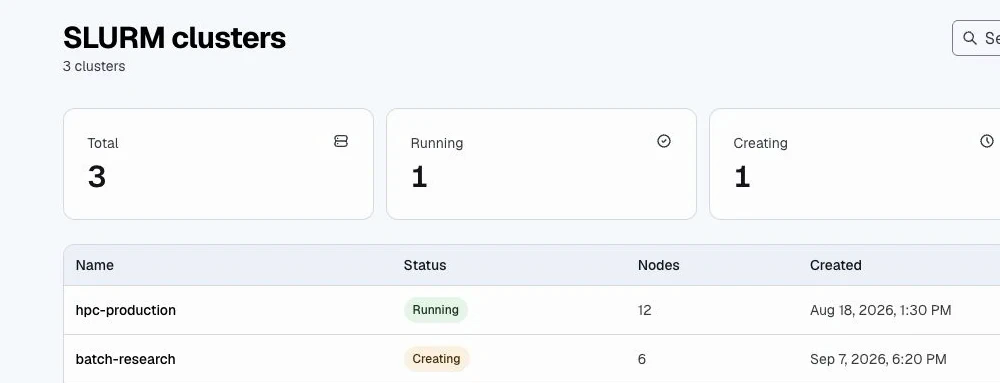
Containerized jobs
Submit containerized jobs to SLURM and follow each job as its state changes.
Templates and scripts
Keep job templates and scripts together and reuse them for the next run.
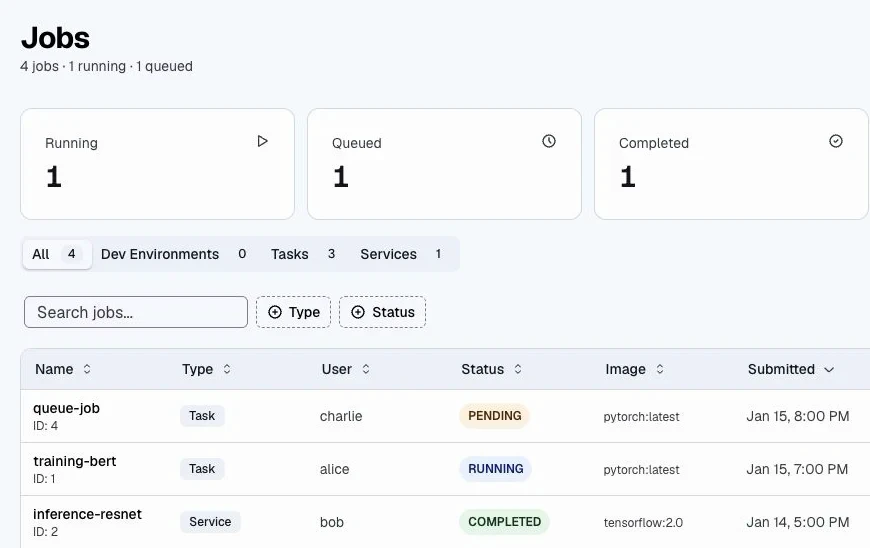
One view of every job
Search and filter jobs by type and status across the project.
Public bio tools
Search sequences with MMseqs2, compare structures with Foldseek and US-align, design proteins with ProteinMPNN, and train predictors on ESM-2, from a form or a REST call.
Pipelines and batches
Connect tools into a pipeline, fan out over many inputs, and rerun only the part that needs it.
Your own tools
Register a Python script or a container image from an allowed registry and run it the same way.
Design and triage
Backbone structure
Input
ProteinMPNN
Design 16 sequences
Protein Properties
Calculate properties
MMseqs2
Cluster sequences
In our cloud or on your own infrastructure.
Choose where it runs based on where your data has to stay. On your infrastructure, bio jobs have no outside network access by default and reach only your object storage and DNS.
| In our cloud | On your infrastructure | |
|---|---|---|
| Clusters and jobs | Included | Included |
| Public bio tools and pipelines | Included | Included |
| Who runs the platform | Supergate | Supergate |
| Where your data stays | Supergate Cloud | Your infrastructure |
| Access to your data | Set out in your agreement | Set out in your agreement |
From chip to platform.
Supergate designs NPUs and SoCs as well as this platform, so the hardware and the software that runs on it come from one team. GPU and NPU machines are to come.
About SupergateSolutions on the platform.
- Managed clustersManaged KubernetesKubernetes clusters for containerized training, services and pipelines.
- Managed clustersManaged SlurmSlurm clusters for batch training and HPC jobs, the way researchers already work.
- Life sciencesBio pipelinesProtein design, sequence search and structure tools, run as pipelines without setting up each one.
- AI inferenceToken FactoryOpen models served through one API, priced per token.